Before the caption
The same silver hat, given two different times.
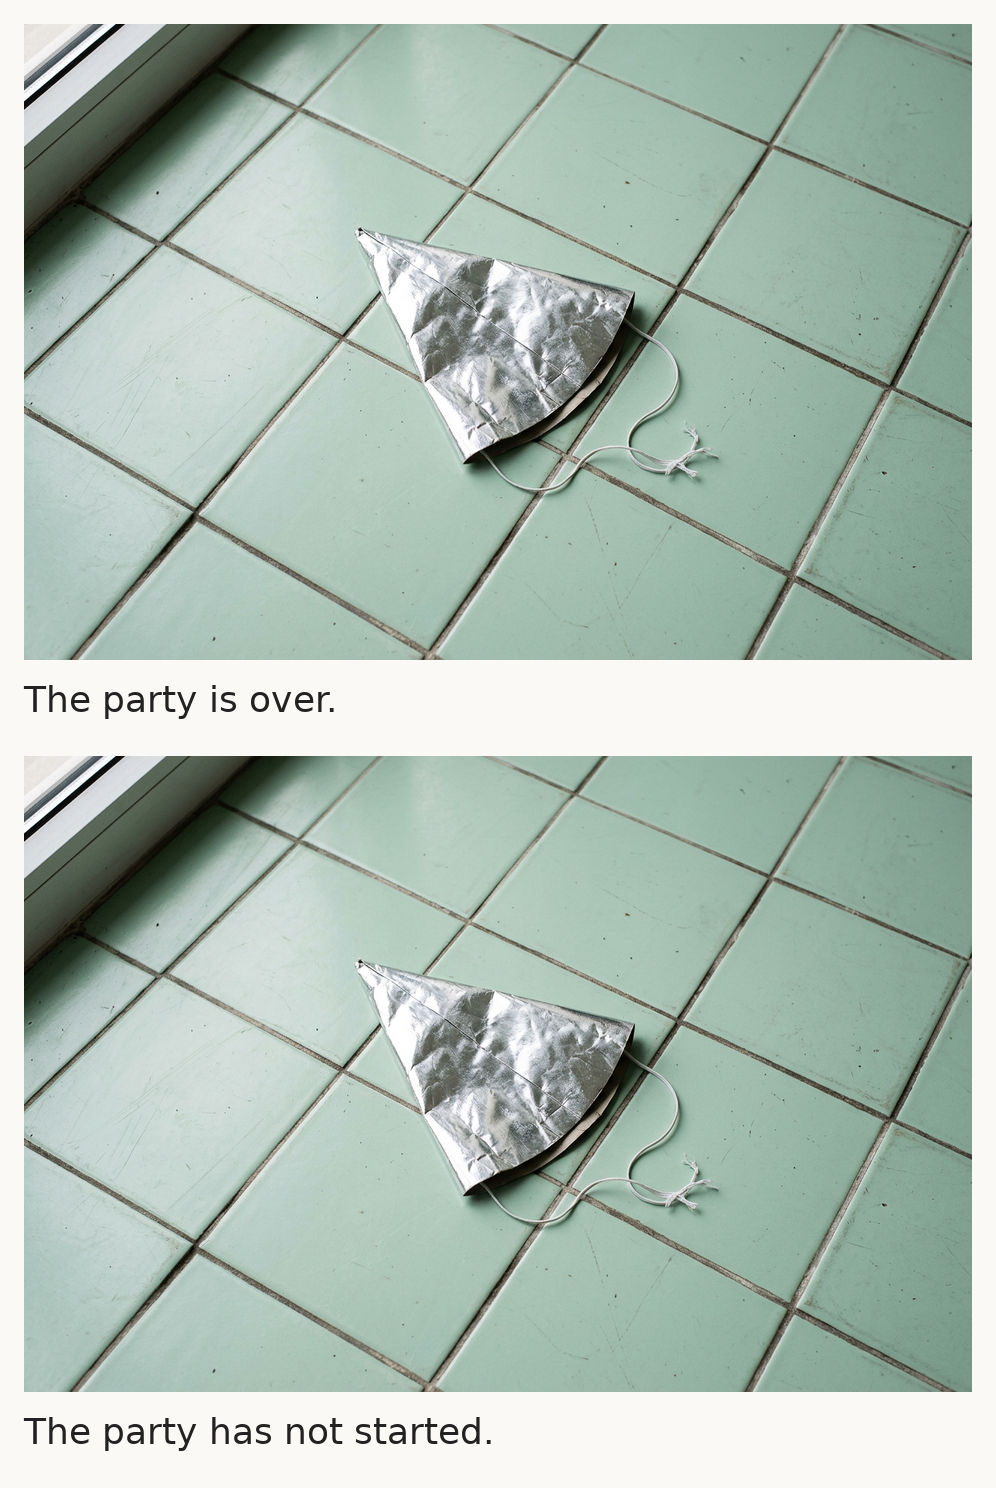
The party is over. The party has not started. Nothing in the image changes between these two sentences.
The first line comes easily to me. For the second, I start inventing preparations: someone might still unfold the hat, or mend its cord. Neither event is in the picture.
I kept the frayed-looking ends that the generator added. They make the second caption harder to believe. The image does not simply agree to everything I write beneath it.
One AI-generated, invented still life, repeated with identical image pixels. I set the captions afterwards. This is a study, not a photograph of an actual party.
パーティーは終わった。パーティーはまだ始まっていない。この二つの文の間で、画像は何も変わらない。
最初の文は、私にはすんなり読める。二つ目を読むと、準備の様子を想像し始める。誰かがこれから帽子を広げるのかもしれない。ひもを直すのかもしれない。どちらの出来事も、画像には写っていない。
画像生成で加わった、ほつれたようなひもの端を残した。それがあると、二つ目のキャプションを信じにくくなる。画像は、下に何を書いても素直に従うわけではない。
AIで生成した架空の静物画像を、同じ画素のまま二度配置した。文字は後から組んだ。これは習作であり、実際のパーティーを撮影した写真ではない。